AI agents can reason, use tools, access data, make decisions, and execute multi-step tasks with limited human supervision. This flexibility makes them more capable than traditional software workflows, but it also makes them harder to observe, evaluate, and control.
Agentic AI monitoring is the continuous observation and analysis of an AI agent’s behavior, decisions, tool usage, data access, performance, security, and outcomes in development and production.
Traditional application monitoring focuses heavily on uptime, infrastructure resources, latency, and system errors. AI agent monitoring needs to go further. Teams need visibility into what an agent did, which tools it used, what data it accessed, whether its actions followed policies, and whether the final outcome matched the intended goal.
This makes monitoring a fundamental part of deploying reliable agentic systems rather than an optional production feature.
What Is Agentic AI Monitoring?
Agentic AI monitoring combines application monitoring, AI evaluation, security monitoring, and observability to track autonomous or semi-autonomous agents.
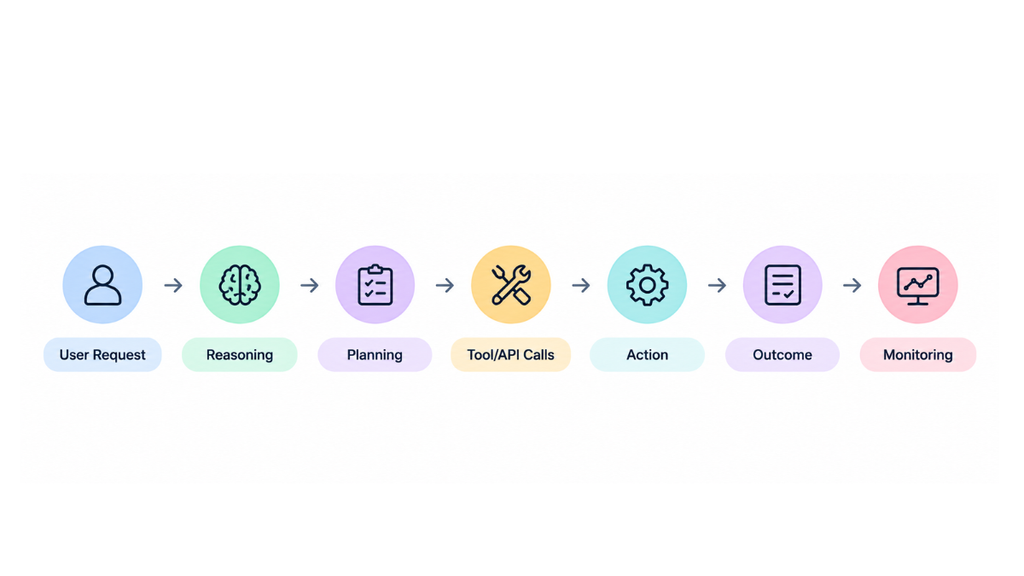
Each step can introduce a different failure.
For example, an agent could retrieve incomplete information, select the wrong tool, make an incorrect decision, expose sensitive data, or repeatedly retry an unsuccessful action.
Monitoring therefore needs visibility across the entire agent execution lifecycle, rather than only checking whether the application is online.
The goal is to maintain:
- Reliability
- Accuracy
- Safety
- Performance
- Policy compliance
- Security
- Cost efficiency
- Desired business outcomes
This makes agentic observability a core part of deploying AI agents into production.
Why AI Agents Need Continuous Monitoring
AI agents are dynamic. Their behavior can change when the model, prompt, retrieved context, tools, permissions, or underlying data changes.
Important sources of risk include:
Model and reasoning failures
An agent can hallucinate information, misunderstand a task, choose an inappropriate action, or produce an incorrect response.
Tool and API failures
Agents may depend on APIs, databases, browsers, vector stores, or other external tools. A failed API call or incorrect tool selection can break the entire workflow.
Data and retrieval problems
Incomplete data, stale knowledge, retrieval errors, or incorrect permissions can cause an agent to make decisions using the wrong context.
Security problems
Agentic systems can face prompt injection, jailbreak attempts, sensitive data leakage, unauthorized tool usage, and excessive permissions.
Behavior drift
Changes to models, prompts, datasets, tools, or workflows can gradually change agent behavior.
Continuous monitoring helps teams detect these problems before they become larger production incidents.
How Agentic AI Monitoring Works
A practical monitoring system collects telemetry throughout the agent’s execution.
For every execution, monitoring can capture:
- User input
- Agent ID
- Model and version
- Prompt and context metadata
- Reasoning or decision metadata
- Tool selection
- API calls
- Retrieved information
- Execution time
- Token consumption
- Errors
- Final output
- Task outcome
This creates a detailed execution record that can be used for observability, debugging, evaluation, and security analysis.
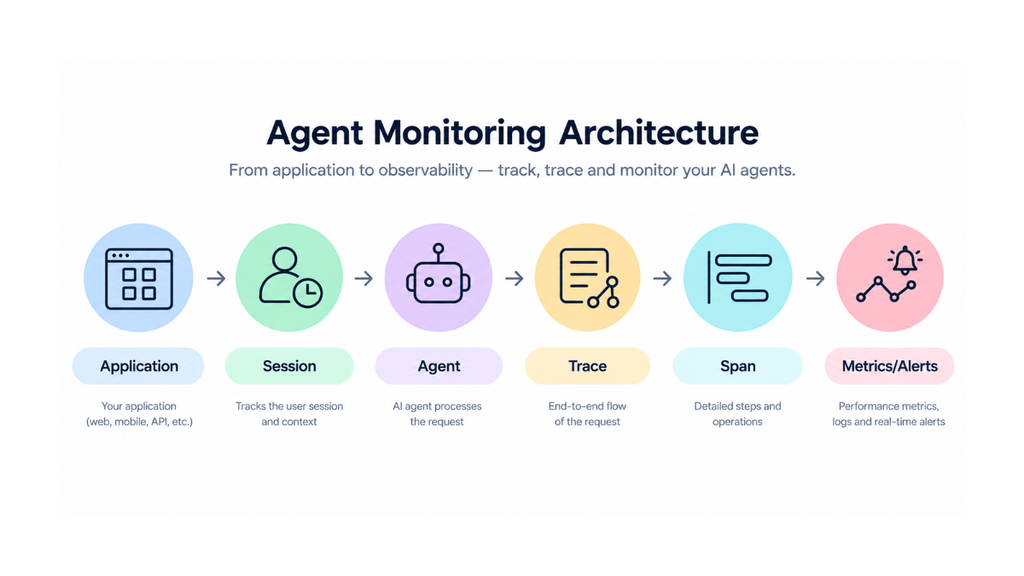
Instrument the Agent Execution Layer
Instrumentation should cover every important part of the workflow.
Model layer: model version, latency, token usage, output quality.
Agent layer: decisions, planning, retries, handoffs, task completion.
Tool layer: tool selection, API calls, permissions, failures, response time.
Data layer: retrieval, data access, context quality, sensitive information.
Outcome layer: accuracy, success rate, policy compliance, and business results.
Tools such as OpenTelemetry can help structure telemetry across applications, traces, and spans.
Agentic AI Monitoring Metrics
Monitoring becomes useful when raw telemetry is converted into measurable signals.
Performance metrics
Track:
- End-to-end latency
- Per-step latency
- Token usage
- API call volume
- Resource consumption
- Cost per task
Agent behavior metrics
Important agent-specific metrics include:
- Task completion rate
- Agent success rate
- Retry rate
- Recovery rate
- Reasoning chain length
- Tool call distribution
- Agent handoffs
- Decision failures
Quality metrics
Measure:
- Accuracy
- Response relevance
- Faithfulness
- Coherence
- Hallucination rate
- RAG health
- Context relevance
- User satisfaction
Security and compliance metrics
Track:
- Policy violations
- Guardrail activations
- Unauthorized actions
- Sensitive data exposure
- Prompt injection attempts
- Access violations
- Unsafe outputs
A strong monitoring system should connect these metrics to actual business outcomes, rather than measuring technical activity alone.
Monitoring Agent Behavior and Tool Usage
Agent behavior should be monitored at the action level.
Teams should establish expected behavior for:
- Which tools an agent can use
- Which APIs it can access
- What data it can retrieve
- Which actions require approval
- What limits apply to spending or API calls
- Which outputs must be blocked
Monitoring tool usage is especially important because an agent’s capabilities depend heavily on external tools.
An agent with excessive permissions can create security risks even when the underlying model is functioning correctly.
This is why agent monitoring should include both visibility and control.
Anomaly Detection, Drift, and Agentic AI Stress Testing
Static monitoring is not enough for dynamic AI systems.
Teams should watch for unusual patterns such as:
- sudden increases in tool calls
- unusually long reasoning chains
- repeated retries
- unexpected API access
- changes in task completion
- increasing latency
- rising token consumption
- abnormal outputs
- new policy violations
Agentic AI stress testing can complement production monitoring by intentionally testing how an agent behaves under difficult or unexpected conditions.
Synthetic monitoring can test:
- malformed inputs
- missing data
- unavailable tools
- unusual user requests
- prompt injection
- permission failures
- model changes
- retrieval failures
This helps identify weaknesses before they affect real users.
Guardrails and Human-in-the-Loop Monitoring
Monitoring should not only detect problems. In high-risk situations, it should also help control agent execution.
A monitoring control plane can trigger actions such as:
- blocking an unsafe output
- stopping execution
- requiring human approval
- restricting a tool
- rerouting a workflow
- changing a threshold
- escalating an incident
Human-in-the-loop validation is particularly useful for high-impact decisions, sensitive data, financial actions, and other situations where autonomous execution should have limits.
The appropriate level of autonomy in agentic AI depends on the risk of the task.
Low-risk tasks can often run automatically, while high-risk actions may require human oversight.
Agentic AI Tech Stack for Monitoring
An agentic AI tech stack can include several layers:
Agent framework: manages planning, reasoning, execution, and tool interaction.
Model layer: provides the underlying large language model or foundation model.
Tool layer: APIs, databases, browsers, search, business systems, and external services.
Data layer: vector databases, knowledge bases, retrieval systems, and application data.
Observability layer: logs, traces, metrics, telemetry, dashboards, and alerts.
Evaluation layer: quality checks, hallucination detection, task evaluation, and safety testing.
Control layer: guardrails, permissions, policy enforcement, and human approval.
Agentic AI Monitoring Best Practices
A reliable monitoring strategy should:
- Define expected agent behavior before deployment.
- Instrument every execution layer, including tools and APIs.
- Track both technical and business metrics.
- Monitor model, prompt, data, and tool changes.
- Use traces to identify root causes rather than relying only on alerts.
- Apply guardrails to high-risk actions.
- Continuously test for security and reliability failures.
- Use human oversight where autonomous decisions carry significant risk.
- Review thresholds when models, prompts, datasets, or tools change.
- Keep monitoring active throughout the agent’s production lifecycle.
Monitoring should become part of the operational architecture, not a feature added after deployment.
Agentic AI Monitoring vs Traditional Application Monitoring
Traditional application monitoring mainly answers:
Is the application working?
Agentic AI monitoring needs to answer:
Is the agent behaving correctly, safely, efficiently, and according to its intended goals?
| Traditional Monitoring | Agentic AI Monitoring |
|---|---|
| Uptime | Task completion |
| CPU/memory | Reasoning and execution |
| Application errors | Agent decisions |
| Request latency | Per-step and end-to-end latency |
| API availability | Tool selection and tool behavior |
| System logs | Agent traces |
| Infrastructure health | Model, data, and behavior health |
| Security events | Prompt injection, data leakage, policy violations |
The second approach requires deeper visibility because the system’s behavior is partly probabilistic and can change over time.
Agentic AI Monitoring for Production
Production monitoring should create a continuous feedback loop:
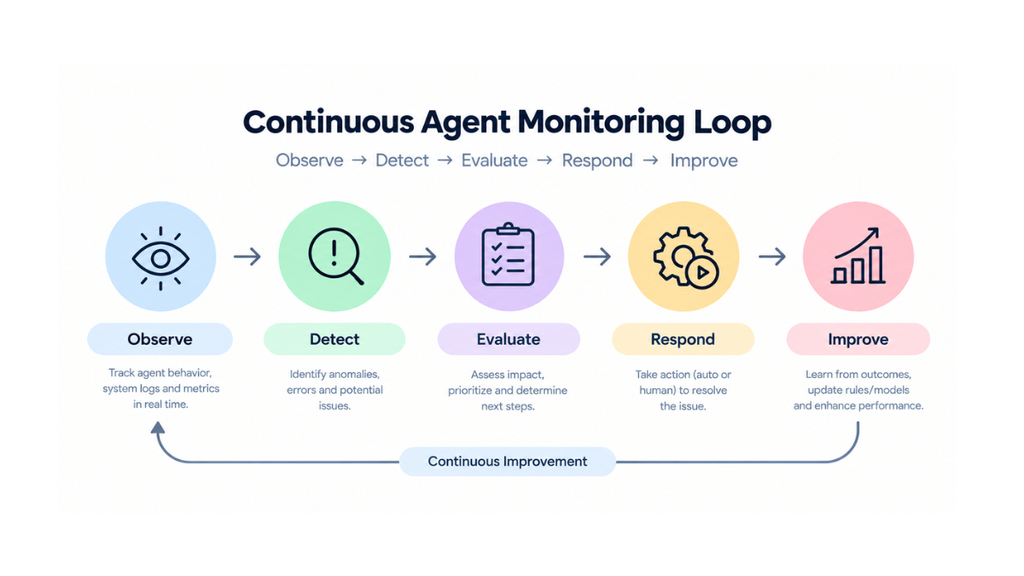
Monitoring identifies failures and unusual behavior. Evaluation determines whether the behavior actually violates expected outcomes. Automated controls or humans can then respond, while the resulting information improves future agent performance.
This approach is particularly important as organizations move from individual AI experiments to enterprise AI systems operating across multiple workflows and tools.
For related implementation concepts, see our guides on AI agent memory, RAG architecture, Model Context Protocol, and Agentic RAG for customer service automation.
Frequently Asked Questions
What is agentic AI monitoring?
Agentic AI monitoring is the continuous observation and evaluation of AI agents, including their behavior, decisions, tool usage, data access, performance, security, and outcomes.
What should you monitor in an AI agent?
Monitor task completion, accuracy, latency, token usage, cost, tool calls, API activity, errors, agent behavior, security events, policy compliance, and output quality.
Why is AI agent observability different from traditional monitoring?
AI agents make dynamic decisions and execute multi-step tasks. Monitoring therefore needs visibility into reasoning, tool usage, context, decisions, and outcomes in addition to normal application performance.
What is agentic AI stress testing?
Agentic AI stress testing evaluates how an agent behaves under difficult, unexpected, or potentially unsafe conditions, such as unavailable tools, malformed inputs, prompt injection, retrieval failures, and high workloads.
Do AI agents need human monitoring?
Not every action requires a human. Low risk tasks can operate autonomously, while high risk actions can use human-in-the-loop approval, guardrails, or automated policy controls.